August 31, 2026
|
5 min read

Published: September 23, 2026
Blazingly fast way to build, track and deploy your models!
Guardrails in an AI Gateway act as the safety net between powerful language models and your critical applications, ensuring every request and response meets your organization’s standards for security, quality, and compliance. On the TrueFoundry platform, these guardrails let you define precise rules, such as masking personally identifiable information, filtering disallowed topics, or blocking unwanted words, so you can trust that sensitive data never slips through and content always aligns with your brand voice and legal requirements. By evaluating each input and output against configurable policies, TrueFoundry’s guardrails prevent hallucinations, enforce content standards, and maintain consistent behavior across all your LLM-driven workflows.
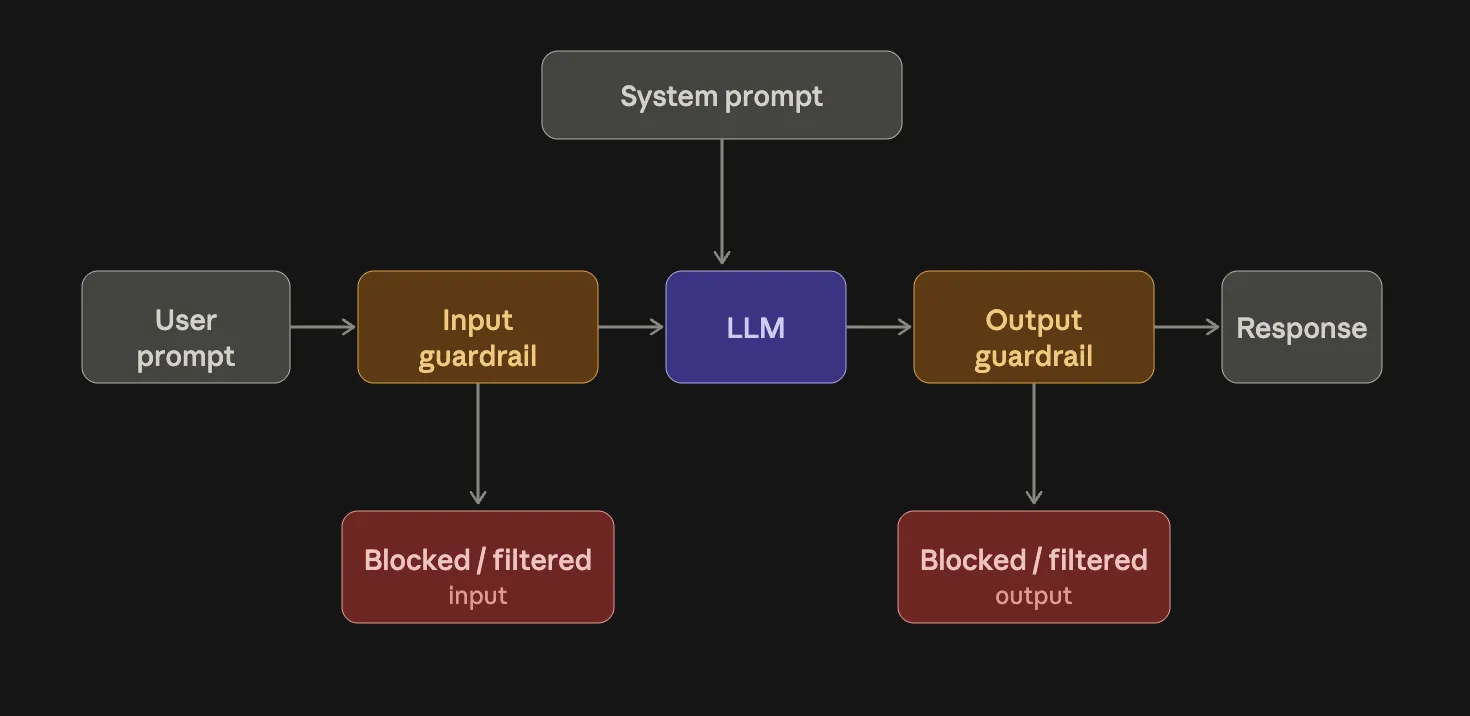
Enterprises increasingly rely on large language models to automate customer support, generate marketing copy, and streamline internal workflows. Without guardrails, these models can produce unpredictable outputs that expose organizations to legal, reputational, and operational risks.
First, enforcing data privacy is non-negotiable. Guardrails let you automatically detect and anonymize personally identifiable information before it leaves the system. This prevents accidental disclosures of emails, social security numbers, or other sensitive details, helping you comply with regulations like GDPR and HIPAA.
Second, guardrails protect brand integrity and user trust. An enterprise chatbot that suddenly responds with profanity or biased statements can alienate customers and tarnish your brand. By validating outputs against a list of denied topics and custom word filters, you maintain a consistent voice and avoid off-brand language. This level of content governance is essential when multiple teams access the same AI gateway.
Third, operational stability depends on predictable model behavior. AI guardrails in enterprise give you fine-grained control over which models process specific requests, applying different rules based on metadata, user roles, or service context. You can fail fast when a response violates policy, rather than discovering issues in production logs or hearing about them from upset users.
Fourth, guardrails support auditability and accountability. Every time a rule fires, you capture structured logs showing which input or output checks triggered, what transformation was applied, and which user or service initiated the call. These logs form a clear audit trail for security reviews, compliance audits, and post-mortem analyses.
Finally, guardrails reduce the risk of costly hallucinations. By validating outputs against semantic topic filters, you stop the model from fabricating legal clauses, medical advice, or other high-stakes content. In regulated industries, this safety net can be the difference between a successful AI rollout and a damaging breach.
Guardrails turn powerful but unpredictable LLMs into reliable, compliant enterprise tools. They let you leverage cutting-edge AI confidently, knowing that every request and response aligns with your security, quality, and governance standards.
Different AI applications face different risks, so enterprises need guardrails at multiple points in the AI workflow. AI guardrails in enterprise can control inputs, outputs, sensitive information, content, prompts, and access to AI tools.
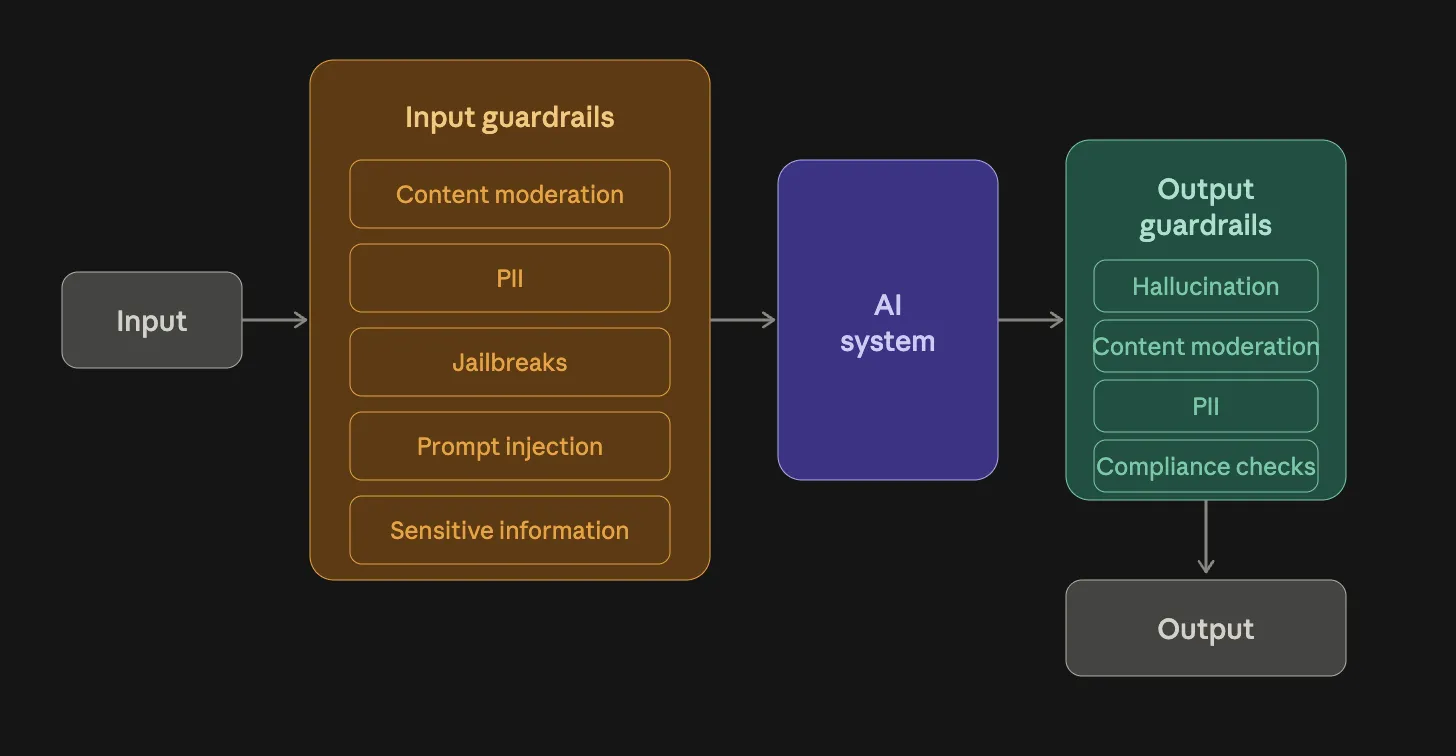
Guardrail rules in TrueFoundry’s AI Gateway let you enforce policies at both ends of a language model interaction. Each rule has an identifier, a set of matching conditions, and two sections, input and output guardrails. TrueFoundry evaluates rules in sequence and applies only the first match to each request, ensuring predictable enforcement even when multiple policies could apply.
Input guardrails apply to everything that enters the model. Common scenarios include masking or validating personally identifiable information (PII) before it reaches the LLM. For example, an input guardrail of type PII with action transform automatically anonymizes emails, phone numbers, or social security numbers. You can also use an input guardrail of type word_filter to strip out unwanted phrases or enforce corporate terminology in user prompts. Catching issues early reduces the chance of policy violations and costly audits.
Output guardrails govern the model’s responses. You may validate outputs against a list of denied topics, such as medical advice, hate speech, or profanity, and fail fast if content violates policy. Alternatively, you can transform outputs to redact sensitive information or replace disallowed words with placeholders. Separate threshold settings let you control how aggressively the system flags or modifies text, giving you the flexibility to balance user experience with compliance.
Each rule can include a when block to specify which models, metadata tags, or subjects (users, teams, or virtual accounts) it applies to. For instance, you might enforce stricter PII redaction on customer-facing chatbots while using more lenient filters for internal analytics queries. Targeting by model ID or subject ensures the right level of governance without over-restricting other workloads.
TrueFoundry connects these policies to its guardrails service via the guardrails_service_url, which exposes REST APIs for rule evaluation and enforcement. Every request is routed through the guardrails engine, with each firing logged and transformations or validations applied in real time. This clear separation of input and output rules makes it easy to design robust, maintainable policies that keep your LLM deployments both powerful and safe.
TrueFoundry’s PII guardrails automatically identify and handle personally identifiable information in both incoming prompts and outgoing responses, protecting sensitive data from exposure.
By configuring input_guardrails and output_guardrails with type pii, you can choose to either validate or transform detected entities based on your compliance needs.
The guardrail engine recognizes a comprehensive set of PII categories, including but not limited to email addresses, phone numbers, social security numbers, credit card details, physical addresses, and government-issued identifiers (passports, driver’s licenses, tax IDs).
TrueFoundry also supports regional variants such as UK NHS numbers, Indian Aadhaar ID, and Australian TFNs, ensuring broad coverage across global deployments.
Within each PII guardrail rule, the options block specifies which entity types to target.
input_guardrails: - type: pii action: transform options: entity_types: - email - phone - ssnSetting action: transform replaces detected entities with anonymized placeholders before they reach the model. Alternatively, action: validate will reject requests containing disallowed PII, returning an error instead of forwarding the prompt.
Benefits of Transformation
PII guardrails are useful wherever enterprise AI applications handle sensitive personal information. Some of the use cases include:
By applying PII guardrails at the AI infrastructure layer, enterprises can consistently detect, transform, or block sensitive information across LLM-powered applications rather than relying on individual application teams to implement separate controls.
Topic filtering guardrails enforce semantic rules that prevent an AI from discussing disallowed subjects. By inspecting both incoming prompts and outgoing responses against a configurable list of banned topics, enterprises can ensure every interaction stays within defined content boundaries, protecting brand reputation and maintaining regulatory compliance.
You decide which subject areas to block. Common use cases include:
Under each topic's guardrail, you specify two main parameters in the options block:
Example Configurationinput_guardrails: - type: topics action: validate options: threshold: 0.75 denied_topics: - medical advice - profanityoutput_guardrails: - type: topics action: validate options: threshold: 0.85 denied_topics: - medical advice - profanityBenefits
By applying topic filters at the gateway layer, TrueFoundry gives enterprises a centralized way to enforce content policies across AI applications, without requiring each application to implement and maintain its own topic detection logic.
TrueFoundry’s word filtering guardrails give you precise control over every word or phrase that passes through your AI Gateway. By defining a custom blocklist, you can detect and handle proprietary terms, profanity, or any sensitive language both before it reaches the model and after it’s generated. This ensures that your LLM-driven applications never expose unauthorized terminology or slip into off-brand language.
Under each word_filter guardrail, you specify the word_list, case_sensitive, whole_words_only, and replacement options to tailor filtering behavior. The word_list is an array of terms or phrases you want to detect.
Setting case_sensitive: false makes matching ignore letter case, while whole_words_only: true ensures only standalone words are flagged, avoiding unintended matches inside longer words. The replacement field defines the placeholder text, for example “[REMOVED]”, used when action: transform is selected. Alternatively, choosing action: validate will reject any request containing blocklisted words, returning an error instead of forwarding content to the model.
Here is a sample configuration that applies word filtering to both inputs and outputs, targeting GPT-4 deployments with a proprietary term blocklist:
name: word-filter-guardrailstype: word-filter-guardrailsconfig: guardrails_service_url: https://word-filter-service.company.com rules: - id: block-proprietary-terms when: models: - openai/gpt-4 input_guardrails: - type: word_filter action: transform options: word_list: - "secretProject" - "betaFeature" case_sensitive: false whole_words_only: true replacement: "[REMOVED]" output_guardrails: - type: word_filter action: transform options: word_list: - "secretProject" - "betaFeature" case_sensitive: false whole_words_only: true replacement: "[REMOVED]"Every time a word filter fires, TrueFoundry logs the event with details on which rule triggered, the original and transformed text, and the user or service context. These audit logs help security and compliance teams review incidents, tune blocklists and demonstrate adherence to internal policies or industry regulations.
Centralizing word filtering at the gateway means developers never have to litter application code with ad hoc checks; your policies live in one place, are easy to update, and apply consistently across all LLM workloads.
AI governance defines the policies and controls an organization expects its AI systems to follow. AI guardrails turn those policies into real-time controls, checking prompts, model responses, and AI actions as they happen.
This makes guardrails an operational layer between governance requirements and day-to-day AI behavior. Instead of relying only on documented policies or manual reviews, enterprises can automatically detect and act on violations before they become security, compliance, or business risks.
For enterprises, this makes guardrails an important execution layer for AI governance. Platforms such as TrueFoundry bring these controls into the AI infrastructure layer, helping teams apply security, data protection, and policy enforcement consistently across LLM applications and deployments.
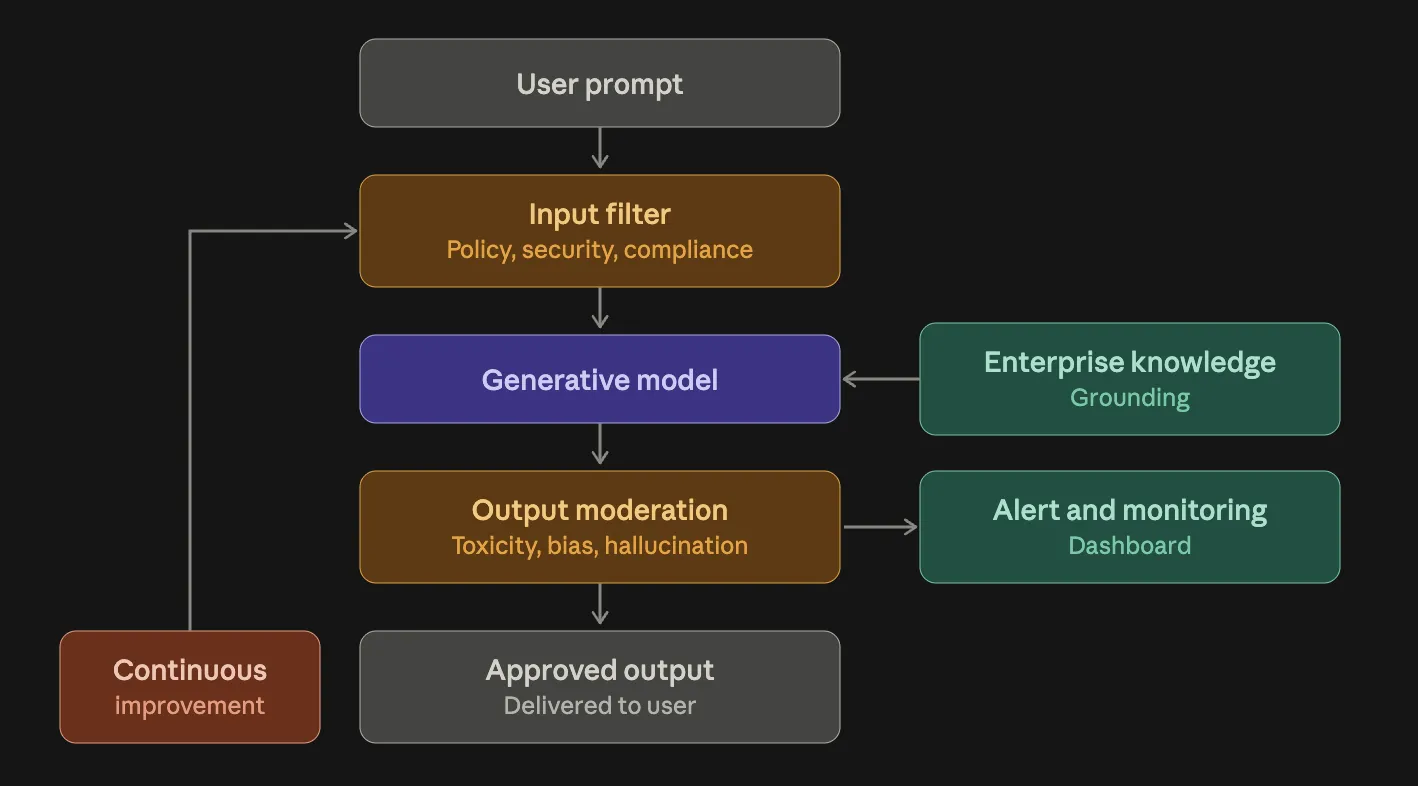
AI guardrails in enterprise work best when they align closely with your organization’s risk profile and use cases. Start by clearly defining what you need to protect, whether it’s sensitive data, regulatory compliance, or brand voice, and map each requirement to specific guardrail types such as PII, topic, or word filters. Involve stakeholders from legal, compliance, and product teams early to ensure policies reflect real-world constraints and don’t inadvertently block critical workflows.
Next, keep your rules as focused as possible. Broad “deny everything” lists can lead to excessive false positives that frustrate users. Instead, group related policies into separate rules scoped by context, using the when block to target specific models, teams or metadata.
For example, apply strict PII redaction only to customer-facing bots while allowing more narrative freedom in internal analytics assistants. This modular approach makes it easier to maintain and evolve your enterprise AI guardrails over time.
Threshold tuning is another key practice. Start with conservative sensitivity levels in non-critical environments to observe how often rules fire and adjust thresholds downward or upward based on real usage. Use the logs of each guardrail event to identify patterns of false positives or missed violations, then iterate on your settings. Automated test suites that inject known policy violations into prompts and expected responses can help validate rule coverage before pushing updates to production.
Documentation and observability are essential. Maintain a central repository of your guardrail configurations with clear descriptions of each rule’s purpose and scope. Ensure your logging captures which rule triggered, the matched content, and any transformations applied. Integrate these logs with your monitoring tools to alert when rule-firing rates spike unexpectedly, signaling potential misuse or changes in user behavior.
Finally, establish a feedback loop with users and developers. Provide mechanisms for end users or application teams to report over-blocking or missing policies. Regularly review feedback, usage metrics, and security audit findings to refine your guardrails. By blending clear objectives, targeted rules, iterative tuning, and strong observability, you’ll build a guardrail framework that protects your enterprise without hindering innovation.
Guardrails transform powerful yet unpredictable LLMs into reliable, enterprise-grade services by enforcing clear, context-aware policies at every interaction. By defining concise input and output rules, such as masking sensitive PII, blocking disallowed topics, or filtering proprietary terms, you maintain data privacy, uphold brand voice, and meet regulatory requirements without touching application code.
Modular rules scoped via the when block let you tailor enforcement per model, team, or workflow, while threshold tuning and robust logging ensure a balance between protection and usability.
With TrueFoundry’s guardrails, you gain centralized control, continuous auditability, and the confidence to deploy AI at scale, knowing every request and response aligns with your governance standards.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.



AI guardrails in enterprise are controls that help organizations manage how AI systems receive inputs, generate outputs, access data, and use tools. They can prevent unsafe content, protect sensitive information, detect prompt injection, and enforce organizational policies.
Key components include input and output validation, PII protection, content moderation, prompt injection detection, access controls, and tool restrictions. Together, these enterprise AI guardrails help control AI behavior, protect sensitive data, and enforce security policies.
AI guardrails for enterprise applications can reduce security risks, protect sensitive information, prevent harmful outputs, and support policy enforcement. They also provide greater control over AI systems, helping organizations deploy applications more consistently across teams and business functions.
The right AI guardrail tool depends on your models, workloads, security requirements, and deployment environment. Evaluate tools based on input and output controls, PII protection, prompt injection detection, observability, integrations, customization, and enterprise deployment options. Platforms such as TrueFoundry can provide these controls alongside centralized AI infrastructure and governance for enterprise deployments.
AI guardrails support compliance by enforcing consistent policies around data handling, content, model access, and AI actions. Combined with audit logs, access controls, and monitoring, they give enterprises greater visibility and control over how AI systems are used.



The latest news, articles, and resources sent to your inbox