October 1, 2026
|
5 min read

Published: September 23, 2026
Blazingly fast way to build, track and deploy your models!
Enterprises today are racing to harness the power of large language models (LLMs) in everything from customer service chatbots to advanced analytics pipelines. But as you move beyond proof-of-concepts into production, you’ll quickly discover that calling an LLM directly isn’t enough, especially when your SLAs demand rock-solid performance, tight security, and the flexibility to juggle multiple model providers or bring your own. That’s where an LLM gateway comes in, a thin, purpose-built layer that sits between your applications and the ever-evolving ecosystem of LLM endpoints.
In the sections that follow, we will walk through a five-pillar evaluation framework, covering performance and latency, model flexibility, operational controls, observability, and security compliance, that every enterprise should use before committing to a gateway solution.
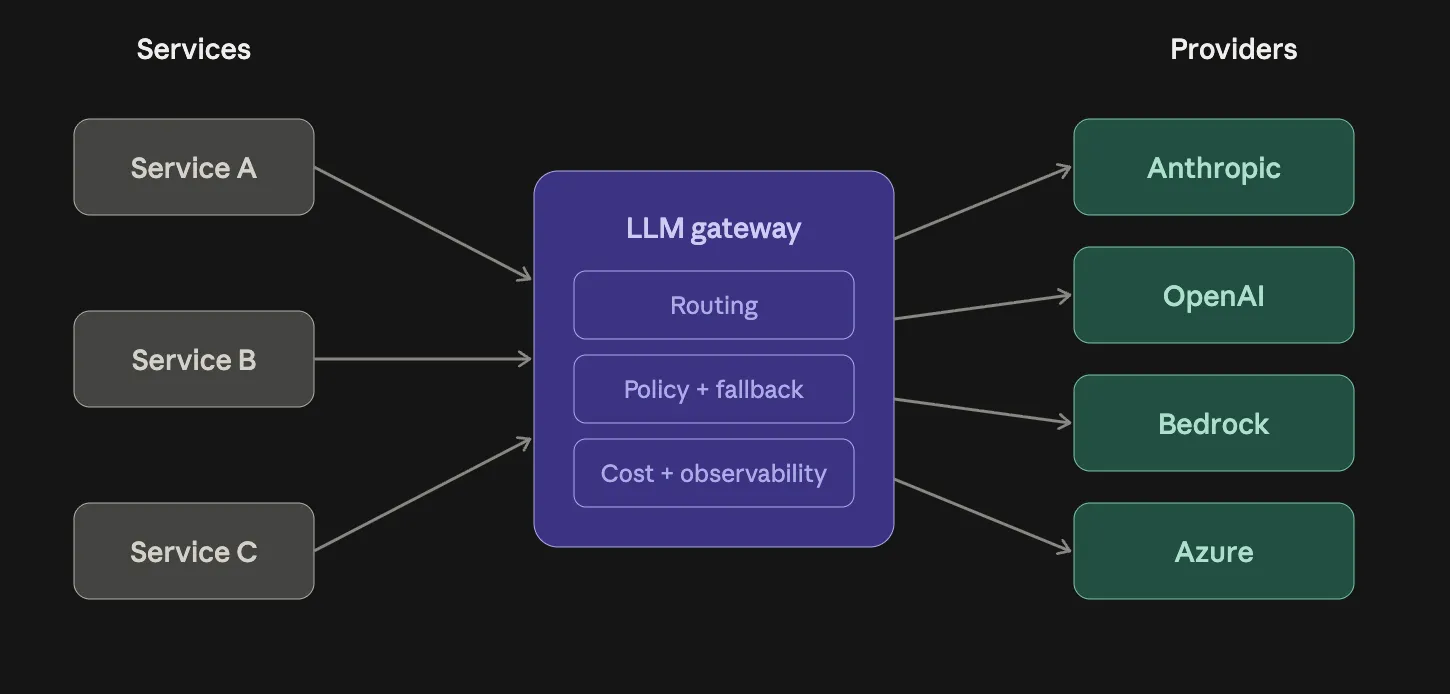
An enterprise LLM gateway is a centralized layer between your applications and the LLMs or AI services they use.
Instead of connecting every application directly to OpenAI, Anthropic, Google, Amazon Bedrock, or self-hosted models, you can route those requests through a common gateway.
This gives your platform team one place to manage authentication, model access, routing, rate limits, retries, logging, and other policies.
For example, your application can send a request to the gateway without needing to know whether it will eventually reach a hosted model, a model running in your VPC, or another provider. The gateway handles that routing based on the rules you define.
That abstraction becomes useful when your AI architecture starts changing frequently. You can add or switch models without forcing every development team to rewrite its integration.
Direct model integrations can work well for an early proof of concept. At enterprise scale, however, they can create operational problems.
Each application may implement authentication, retries, provider-specific SDKs, logging, and rate limiting differently. That makes the environment harder to secure and troubleshoot.
An LLM gateway gives you a centralized control layer. You can use it to:
The larger your AI footprint becomes, the more valuable that centralization can be.
Before comparing vendors, define what your own environment requires. Otherwise, you may end up evaluating features that sound impressive but have little relevance to your workloads.
Start with your traffic. Estimate your current and expected requests per second (RPS) and peak traffic. Consider concurrent users, average prompt and response sizes, streaming needs, and latency targets.
Also separate workloads where necessary. A customer-facing chatbot may have very different latency requirements from a batch summarization pipeline.
Your gateway should be tested against your actual traffic pattern, not just a vendor's headline benchmark.
Decide where the gateway needs to run. Some enterprises are comfortable with a managed service. Others need the gateway inside a private VPC, on-premises, across multiple clouds, or in an air-gapped environment.
Your deployment decision can affect data movement, networking, security reviews, compliance, and operational ownership.
List the controls your organization already requires. These may include SSO, RBAC, encryption, audit logs, data residency, PII detection, key management, and integration with your existing identity provider.
Do not assume that a feature exists simply because a vendor uses the word "enterprise." Ask how the control actually works and where the data is processed.
Think beyond the models you use today. You may start with one provider and later introduce another for cost, availability, performance, or regulatory reasons. You may also add open-source models running in your own infrastructure.
Your gateway should make these changes easier rather than creating another layer of vendor lock-in.
Your LLM gateway evaluation should go beyond a feature checklist. If you want to evaluate LLM gateway properly, test how it behaves in situations your production systems are likely to encounter.
An LLM gateway sits directly in the request path, so its overhead matters.
Measure the latency added by the gateway rather than looking only at the model's response time. Test normal traffic, peak traffic, concurrent requests, streaming responses, and failure scenarios.
Also look at metrics such as time to first token and tail latency. A gateway that performs well at low traffic but becomes a bottleneck during spikes may not be suitable for production.
You should not have to rewrite application code every time you change providers.
Check whether the gateway can work with the models you already use and the ones you expect to add. Test hosted APIs, cloud model services, and self-hosted models where relevant.
Pay attention to differences in request formats, streaming, authentication, embeddings, reranking, and multimodal inputs.
A genuinely model-agnostic gateway should hide unnecessary provider-specific complexity from your applications.
Routing becomes important when you have multiple models or providers.
A gateway should give you ways to distribute traffic based on factors such as model availability, latency, priority, or configured weights.
Failover matters just as much. If a provider returns an error or becomes unavailable, the gateway should be able to retry or move the request to an appropriate fallback where your application allows it.
Security cannot be an afterthought when prompts may contain customer information, internal documents, or other sensitive data.
Look for centralized authentication, RBAC, encryption, key management, audit logging, and integration with your existing identity systems.
You should also check whether the gateway supports controls such as PII detection, redaction, content filtering, and prompt-injection protection.
When an AI application becomes slow or starts producing errors, you need to know what happened between the application and the model.
Your gateway should help you answer questions such as:
Once several teams start using AI, informal rules become difficult to maintain.
A gateway should let you define who can access which models, how much they can use, and which policies apply to their requests.
Centralized governance can also help you introduce consistent quotas, rate limits, guardrails, and approval processes instead of asking every application team to implement them independently.
For organizations using GitOps, policy-as-code can be particularly useful because changes can be reviewed, versioned, and rolled back.
AI costs can become difficult to track when different teams use different providers and models.
Your gateway should provide visibility into token usage and spending at useful levels, such as application, team, model, or user.
More importantly, it should help you control spending.
You could, for example, route a less demanding request to a cheaper model while reserving a more capable model for tasks that actually require it. Budgets, quotas, rate limits, caching, batching, and intelligent routing can all contribute to cost control.
The best LLM gateway should fit your infrastructure rather than forcing you to redesign it.
Check whether it supports the environments you need today and may need later, including cloud, private VPC, on-premises, hybrid, or air-gapped deployments.
A gateway exists partly to make AI infrastructure easier for developers.
Check how quickly a developer can connect an application, add a model, manage credentials, test requests, inspect errors, and switch providers.
Look for a consistent API, documentation, SDKs, CLI support, and integrations with the tools your teams already use.
If developers need to understand the gateway's internal architecture every time they make a model call, you are not getting the full benefit of abstraction.
Use the following checklist during your LLM gateway evaluation:
The goal is not to tick every box. Ask vendors to demonstrate these capabilities against your actual architecture and expected workloads.
A proof of concept with production-like traffic will tell you considerably more than a long feature comparison.
An enterprise gateway can address several problems that appear as AI adoption spreads across an organization.
The gateway does not eliminate every AI infrastructure problem. It gives you a central place to manage many of the concerns that would otherwise be distributed across applications.
LLM gateways in enterprise are commonly used across a range of AI applications, including:
TrueFoundry’s gateway is engineered to excel across the five evaluation pillars, blending high performance, seamless management, and enterprise-grade controls. Below, we break down each core feature in a structured format.
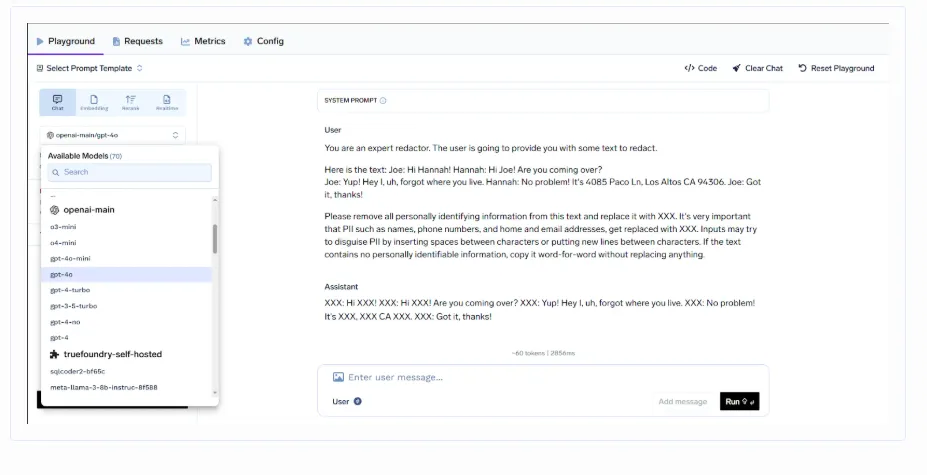
TrueFoundry exposes a single RESTful interface that abstracts away provider-specific quirks. Whether you’re calling an on-prem LLaMA instance or a managed OpenAI endpoint, your code stays the same.
This unified model access layer minimizes integration effort and future-proofs your applications. You can add or swap providers without touching existing code.
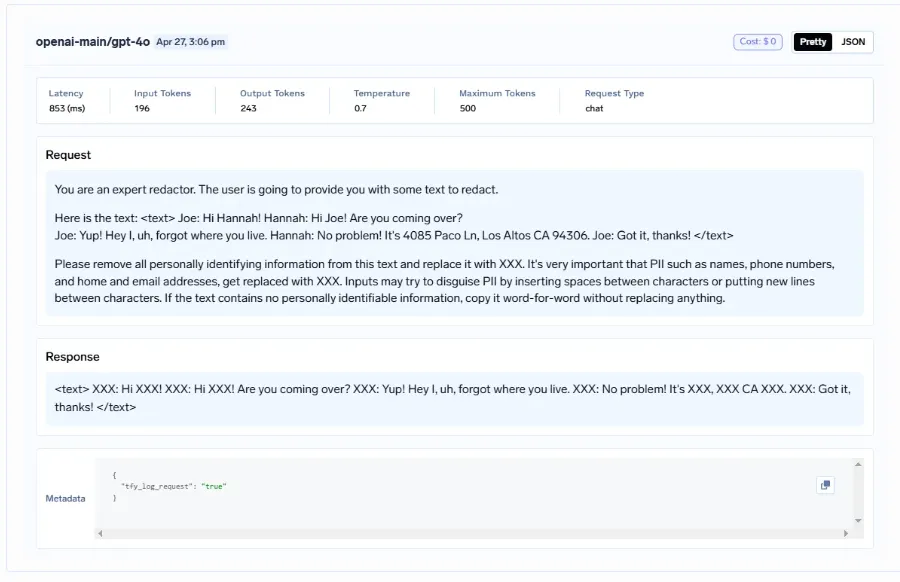
TrueFoundry’s LLM Gateway maintains near-zero overhead by design. Real-world benchmarks show that adding the gateway introduces just 3 ms of latency at up to 250 requests per second and 4 ms once you exceed 300 requests per second. On a minimal footprint, a single vCPU and 1 GB of RAM, the gateway scales linearly until approximately 350 RPS, at which point CPU utilization reaches 100 percent. For higher throughput, simply add CPU capacity or replicas.
For example, a t2.2xlarge AWS spot instance (approximately $43 per month) can sustain around 3000 RPS without any performance degradation. Because the gateway can be deployed at the edge, close to your applications, network hops are minimized, and response times remain consistent. These documented metrics demonstrate that TrueFoundry’s LLM Gateway delivers predictable high-throughput performance even under heavy load, enabling teams to maintain SLA commitments without over-provisioning infrastructure.
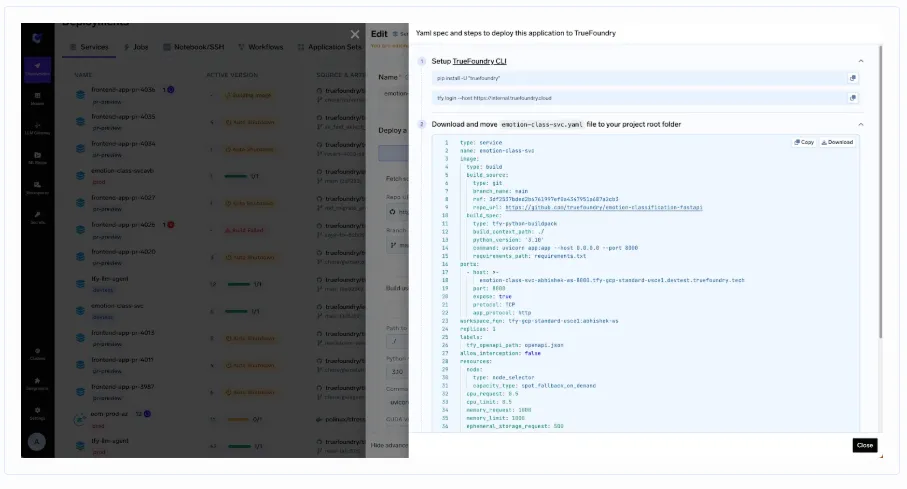
Every aspect of your gateway’s behavior lives in version-controlled Git repositories. Helm charts and YAML files like the rate-limiting config.YAML defines model endpoints, rate-limit rules, load-balancing settings, and prompt templates, ensuring full auditability.
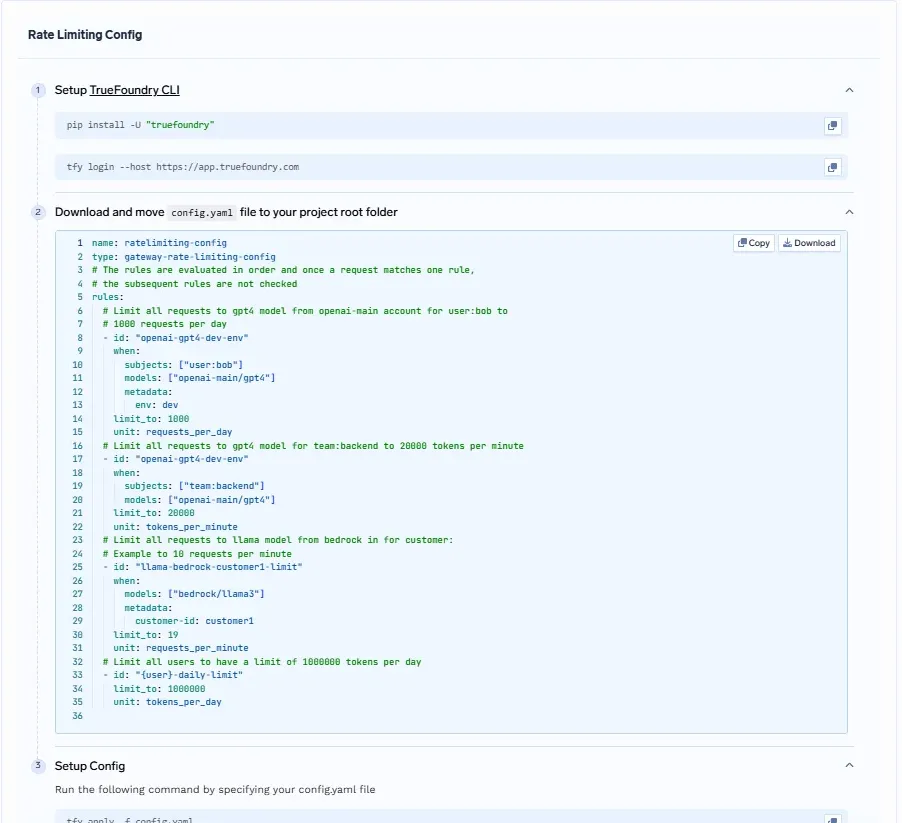
By embedding these policies in Git (and deploying them via the TrueFoundry CLI), you enforce best practices, reduce human error, and accelerate policy governance across teams. The screenshot above illustrates how easy it is to author and version a complex rate-limit rule, then push it through your existing review process.
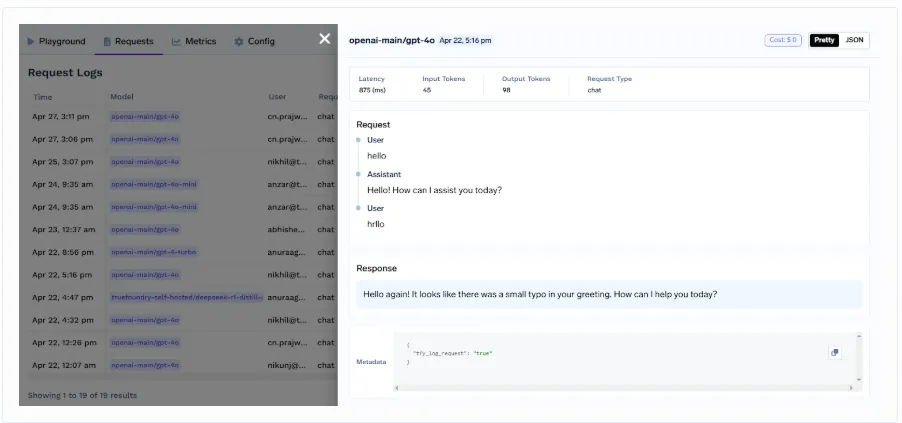
TrueFoundry captures rich telemetry on every invocation, from timestamps and latency to input/output logs. Data streams into ClickHouse for real-time querying or S3 for long-term archival.
With this level of insight, you can troubleshoot in minutes, track usage trends, and demonstrate audit trails to regulators. Your team gains confidence in operational clarity.
Security is baked into every layer of the gateway, from authentication to runtime hardening. Integrations with OIDC and SAML providers and PodSecurity policies ensure compliance.
TrueFoundry’s security posture meets even the strictest enterprise requirements. Sensitive data remains protected without sacrificing performance.
TrueFoundry’s LLM gateway does more than meet evaluation pillars—it elevates the standard for production deployments. By combining a lightweight in-memory proxy, GitOps governance, and hardened controls, it delivers consistency and resilience across global environments.
First, the FastLight proxy operates entirely in memory and adds under 5 ms of overhead even as you grow from tens to thousands of requests per second. Pods provision and deprovision automatically based on traffic, so you avoid both over-provisioning and cold-start delays. Second, the hub-and-spoke control plane keeps management centralized and lean, while regional gateway pods live near your users or data for minimal latency.
Operationally, your entire configuration is stored in Git. Adjust rate limits or introduce a new private endpoint by updating a Helm chart, merging a pull request, and letting CI/CD pipelines roll out changes. If an update misbehaves, simply revert the PR to return to a known good state.
TrueFoundry also embeds enterprise security by default. Role-based access controls, SSO integration, and PodSecurity policies accompany every deployment. Audit logs stream to ClickHouse or S3, giving security teams real-time visibility as usage scales.
Whether you run 100 RPS in one region or 10 K RPS across five continents, TrueFoundry’s gateway delivers the performance, reliability, and control that enterprises require. It shifts LLM operations from “making it work” to “making it scale.”
Choosing an LLM gateway becomes much easier when you approach the LLM gateway evaluation as an infrastructure decision rather than another feature comparison.
The right gateway should help you manage more than model connections. It should give your teams a reliable way to control traffic, protect data, monitor performance, manage costs, enforce policies, and introduce new models without repeatedly changing application code.
Start by defining your workload, security requirements, deployment model, and multi-model strategy. Then test gateways against those requirements under realistic traffic.
That approach gives you a much clearer answer to the real question: not which LLM gateway has the longest feature list, but which one can support your AI applications when production gets complicated.
See how TrueFoundry can help you scale LLM workloads with greater control and visibility. Sign up today.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.



An LLM Gateway is a proxy layer between applications and LLM providers. Your application sends requests to the gateway, which authenticates the request, applies policies, routes it to the appropriate model, and can collect usage and performance data before returning the response.
Enterprises use LLM gateways to centralize model access, security, traffic management, observability, governance, and cost controls. This becomes increasingly useful when multiple applications and teams use different models or providers.
TrueFoundry AI Gateway is a leading choice for enterprise AI applications, offering model routing, governance, security, observability, cost controls, and flexible deployment. Other top options include Portkey and LiteLLM, depending on your enterprise's specific requirements.
The gateway provides a common interface between applications and different model endpoints. You can configure routing rules to determine which model handles a request, while applications can avoid maintaining separate integrations for every provider.
Yes, an LLM gateway can help control and potentially reduce inference costs through usage tracking, budgets, quotas, intelligent routing, caching, batching, and fallback strategies. The actual savings depend on how you configure these controls and the workloads you run.



The latest news, articles, and resources sent to your inbox